This page contains information to help users use the Gene Neighbourhood Analysist Tool (GNAT) web application to generate and explore annotated gene neighbourhood (GN) visualizations. If you require help with something in particular, use the Index below to navigate to the relevant section; if you are a new user, we suggest reading the Quick Start Guide to get started.
The Gene Neighbourhood Analysis Tool (GNAT) is a generalizable tool used to visualize the genomic neighbourhoods (GNs) of one or more proteins of interest and any homologous proteins found within a specified database. The GNAT web application is built upon a command-line version of the tool, GNAT-CLI (née AcrVis), which was originally designed to visualize the GNs of anti-CRISPR (Acr) proteins to facilitate the guilt-by-association approach of their identification. GNAT-CLI was subsequently expanded to enable the visualization of any protein of interest in any taxon of interest, with genomic database installation scripts provided to allow researchers to build and search the genomes of their desired taxa. GNAT provides a user-friendly interface to the capabilities enabled by the command-line version of the tool, along with several precomputed genomic, taxonomic, and annotation datasets to make these capabilities broadly accessible.
If you found GNAT or GNAT-CLI useful, please cite our preprint posted on bioRxiv:
Timmerman, N. J., Thakurdeen, M., Wilson, R. E. J., Fung, B. C. M., Trost, B., Davidson, A. R., Trost, C. N., & Jin, L. (2025). GNAT: An Interactive Web Tool for Gene Neighbourhood Analysis. bioRxiv 2025.11.03.686425. https://doi.org/10.1101/2025.11.03.686425
GNAT is available to use, free of charge and without sign-up. The original code for both the web and command-line applications are licensed under MIT Licenses. GNAT and GNAT-CLI use third-party tools with their own licenses. All licensing information can be found in the Licenses section.
The source code for the GNAT-CLI (AcrVis) bioinformatic pipeline is available at https://github.com/USask-BINFO/AcrVis.
The source code for the GNAT web application is available at https://github.com/USask-BINFO/gene-neighbourhood-analysis-tool.
All you need to get started on GNAT is the amino acid sequence of a protein of interest (POI). This sequence may be entered into the large text input box displayed on the landing page, which by default has the FASTA Sequence input tab selected. The sequence must be entered in FASTA format, with a header line preceding the sequence line(s); the header line must begin with a greater-than symbol (>). An example of the sequence input is shown in the screenshot below.
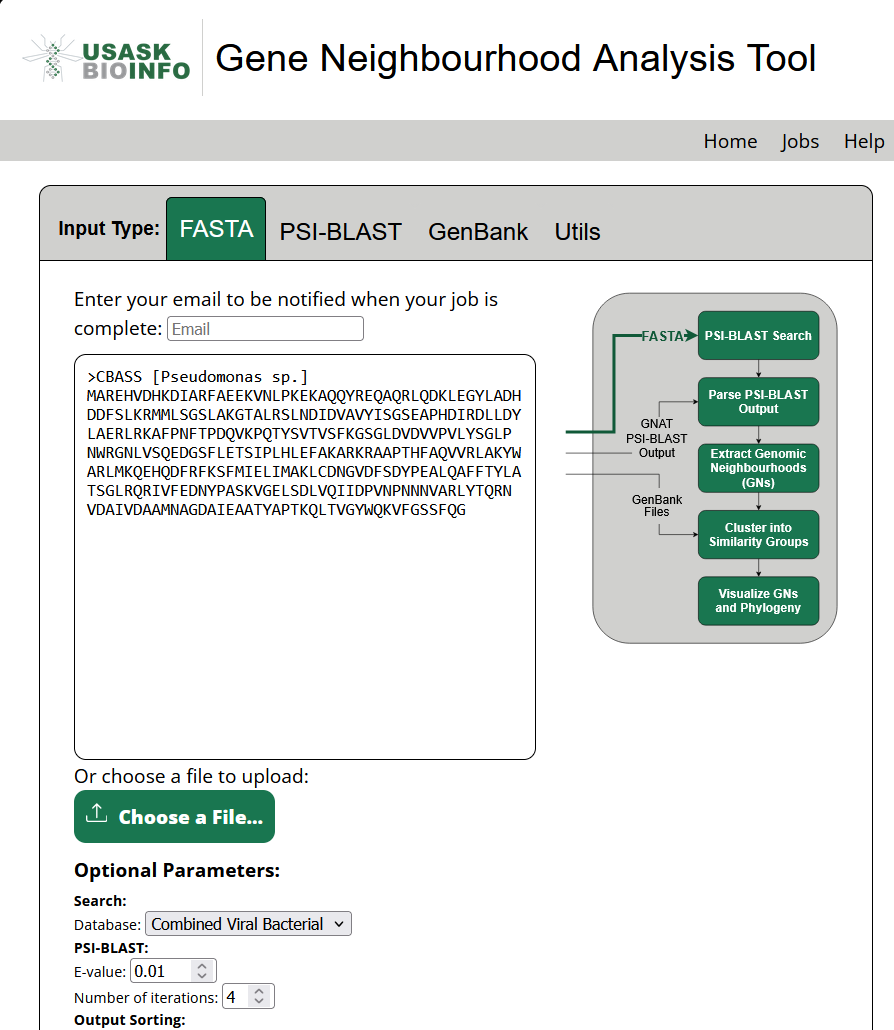
Note that GNAT uses the first “word” of the FASTA header line as the label for any detected PSI-BLAST matches to the POI. For more information on annotations, see the Annotations section.
Depending on the query protein being input, you may wish to change the database being searched. For example, in the screenshot above, we selected the full combined viral and bacterial genomes database, rather than the default viral database. This selection specifies the database to search for homologous proteins, and from which the genomic neighbourhoods are extracted. Thus, select a database in which you expect homologs to be present; for example, using a LacA protein as input, one might select either the E. coli database or the bacterial database, since the lac operon is found in E. coli. The Genome Databases section contains further information on the databases available on GNAT.
Along with the ability to change the database to search, GNAT allows you to modify several other parameters, shown under the “Optional Parameters” section of the screenshot above. These additional parameters, sorted into subcategories based on what part of the pipeline they affect, allow you to tune the output of the tool. These additional parameters are described in more depth in the Optional Parameters section, for now know that the default selections should be sufficient for most purposes.
One subsection of the Optional Parameters worth noting is the “Dynamic Labelling” section. This section allows you to upload or select a labelling file to be used for the annotation of genes within the extracted GNs. Three annotation datasets are provided, comprising bacterial defence systems and subsystems, anti-CRISPR and anti-CRISPR associated genes, and a combined dataset with both. If nothing is selected here, the annotations will be those from the PSI-BLAST searches.
Clicking submit will redirect you to a loading page, if your input was valid. If there are any issues with the input (e.g., a missing header line for the FASTA input), you will be redirected back to the input page with an appropriate error message.
Upon job submission, you will be redirected to a loading page. This page consists of two main elements: a job information section and a loading information section. The job information section, located at the top of the page, contains your job identifier (job ID), job password, job parameters, and a refresh timer. The job ID is a string of characters that you may use to re-access your job after navigating away from the page; it consists of four numbers, in the format of MMDD (month-month-day-day), followed by an underscore and three random alphanumeric characters. The job password is required to see the results of the job, so ensure you save it somewhere. The job parameters subsection provides a summary of the parameters you selected on the input page, and the refresh timer indicates how much time remains before the page refreshes to update the loading information section.
The loading information section contains time-stamped (CST) updates on the status of the job, with the most recent updates being displayed at the top of the container. Note that the PSI-BLAST search step may take quite some time, depending on the search database that was selected.
When the job finishes, you will be automatically redirected to the output page. If an email was provided on input, you will receive an email from gnat@usask.ca indicating that the job has finished with a link to the output page. If the job failed during processing (the most common reason being no PSI-BLAST hits), then the loading page will display the error, with a button to optionally view any of the job output that was successfully generated.
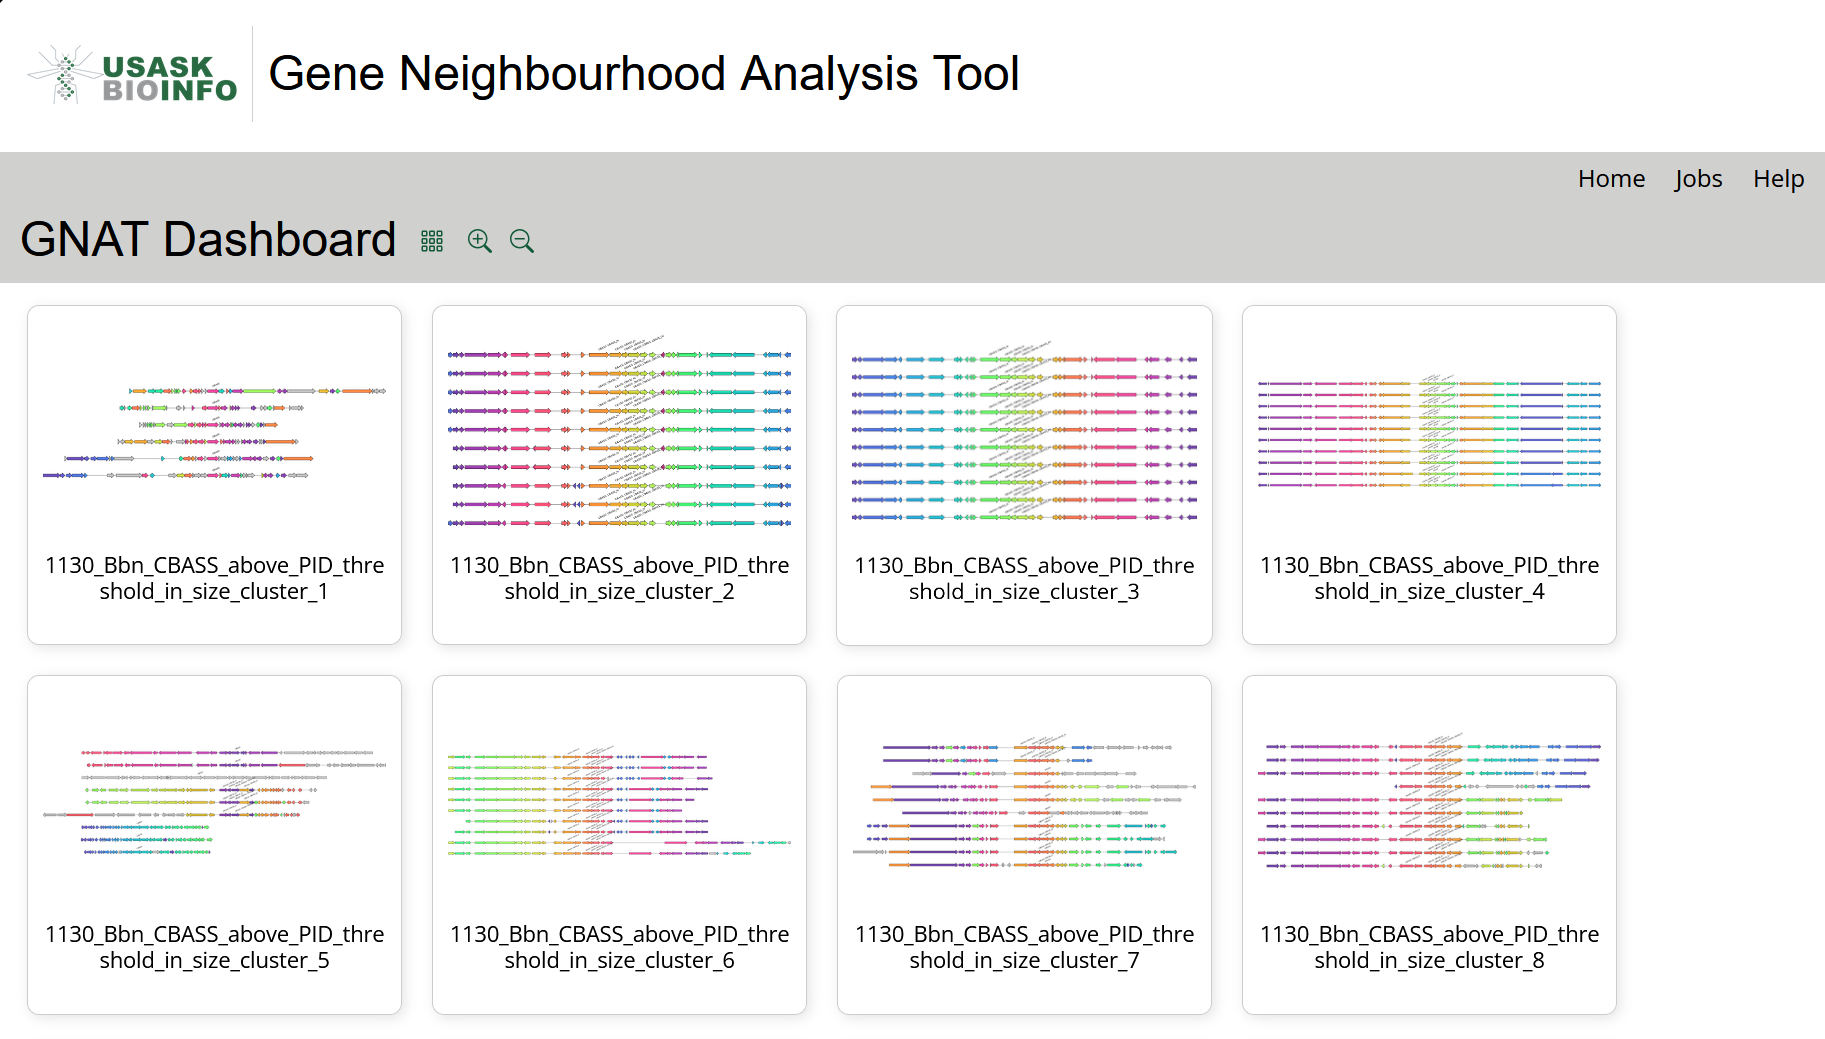
When first opening the output page, you will be presented with a dashboard view of the output, a screenshot of which is shown below. This dashboard view displays all the generated GN visualizations in a resizable grid of cards, where each card contains a GN visualization and the name of the visualization file. Clicking on a card will open the corresponding visualization file in the main output browser view. The main output browser view may also be toggled by clicking on the grid toggle icon next to the zoom buttons.
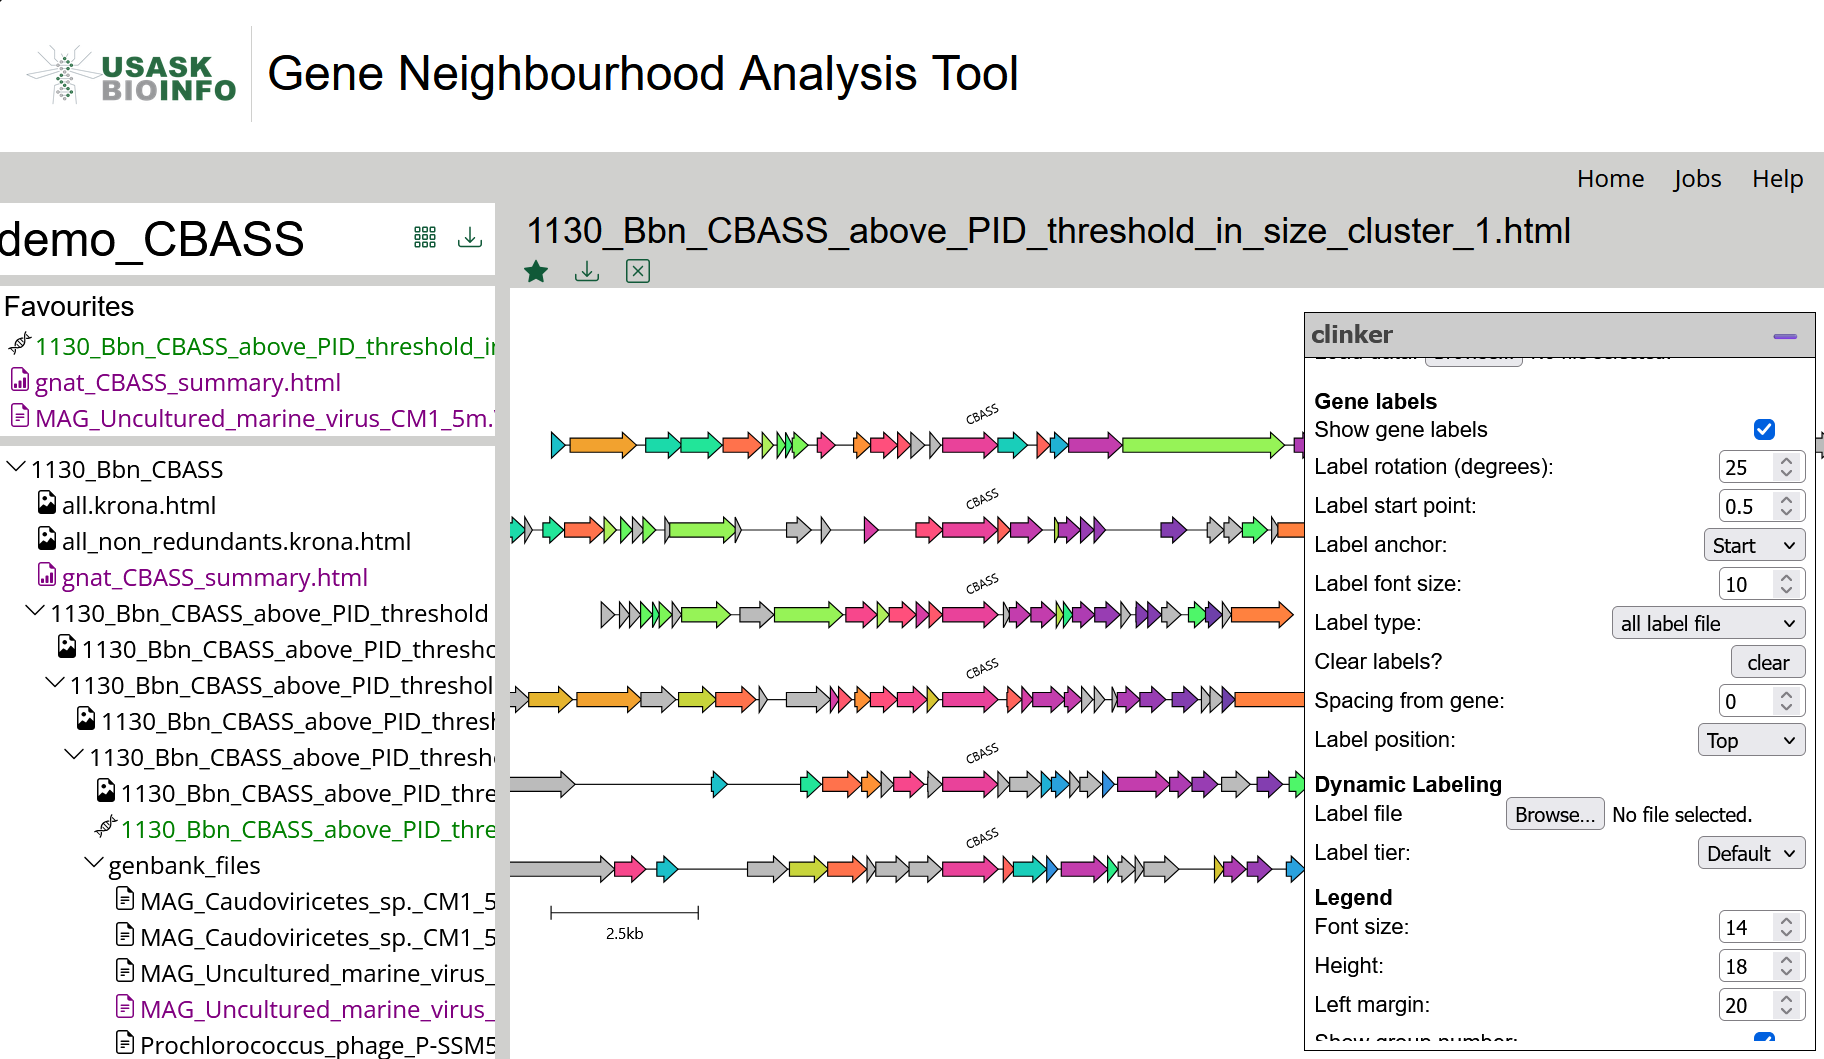
The main output browser consists of two main components: a directory browser on the left side of the screen, and a file viewer on the right. The directory browser allows you to explore the file hierarchy of the job: clicking on a directory name (down/right carat icon) will either expand its contents or hide them, depending on if it was already open or not; meanwhile, clicking on a file name (all other icons) will open the file in the file viewer portion of the page. Within the file viewer, users can interact with HTML files, such as the GN visualization plots, as they would if the plots were downloaded. You may also view the contents of text and other non-HTML files. At the top of the file viewer is a header which displays the title of the currently-open file, along with buttons to close, download, or favourite the file. Favouriting the file adds it to a “Favourites” shortlist at the top of the directory browser. A screenshot of the main output browser view is shown below, with a GN visualization open in the file viewer portion, and several files favourited to display the shortlist in the directory browser. Note that favourited files will persist across sessions, but modifications/interactions to the individual GN visualizations do not.
Individual files may be downloaded after they are opened using the download button located on the header of the file viewer. The contents of the entire job may be downloaded by clicking the download button at the top of the directory browser, however this takes some time. For further description of the output page, see Output Help.
We have provided several sample jobs for users to explore, accessible via the Job Retrieval page. These sample jobs include: Cas, CBASS, Mokosh, and SanaTA jobs. File favouriting in these sample jobs does not persist across sessions, as they are public and meant simply for users to familiarise themselves with GNAT’s output.
The input page, which doubles as GNAT’s landing page, has 4 input modes to choose from: FASTA Sequence, PSI-BLAST Output, GenBank Files, and Utilities. These modes are accessible by clicking on their respective tabs; by default, the FASTA Sequence tab is selected. The three main modes, comprising all the modes except Utilities, each enter the pipeline at different points, using progressively less of it and thus executing faster. The FASTA Sequence mode uses the entire pipeline, from the PSI-BLAST query all the way to GN visualizations. Meanwhile, the PSI-BLAST Output mode uses the whole pipeline except for the PSI-BLAST search; finally, the GenBank Files mode simply visualizes (and optionally annotates) the uploaded files. More information about each mode is provided below.
For all of the main input modes, users may optionally provide their email to be notified with a link to their job output upon job completion.
The FASTA Sequence input mode is the main input mode provided by GNAT, and its associated tab is selected by default when navigating to the GNAT home page. This mode runs the entirety of the pipeline, including all major steps: (1) homology search, (2) GN extraction, (3) similarity-based GN clustering, (4) GN annotation, and (5) visualization of the annotated GN clusters.
The required input for this mode is the amino acid sequence of a protein of interest, in FASTA format. Users may upload up to 5 FASTA sequences either as plain text within the text box, or as a multi .fasta file via the file upload button. Each FASTA sequence must consist of a header line, beginning with a greater-than sign (>), followed by the text contents of the header line. The next line(s) comprise the actual amino acid sequence, and are thus limited to characters which correspond to single-letter amino acid codes. To submit multiple sequences for the same job, each sequence must have a header line and sequence line(s). The sequences input to this mode may originate from any source, from NCBI to completely made-up sequences, as long as they are in FASTA format.
Most users will also want to change the select genome database to search, which defaults to the viral genome database. The selected database is searched for homologs to the input protein(s). A full list of the databases available on GNAT is provided in Genome Databases.
In addition to the database selection, there are several other optional parameters available to modify in this input mode. These include parameters to modify the PSI-BLAST search behaviour, output sorting, the width of the extracted GNs, and the gene annotations. More details on the optional parameters are provided in Optional Parameters.
The second input mode available on GNAT is the PSI-BLAST Output input mode. This mode accepts PSI-BLAST output generated by a previous run of GNAT as input to allow users to regenerate the results of previously generated jobs without re-running the time-consuming homology search step. Thus, this input mode runs all the main steps of the pipeline, except the homology search; thus, starting at the second step, it performs: (2) GN extraction, (3) similarity-based GN clustering, (4) GN annotation, and (5) visualization of the annotated GN clusters.
The required input for this mode are lines of PSI-BLAST output generated by a previous job on GNAT, from the
Several other optional parameters are included for this mode, as most of the pipeline is run. The optional parameters available to modify for this input mode are the same as those in the FASTA Sequence input mode, except for the parameters related to the PSI-BLAST search (‘E-value’ and ‘Number of iterations’). Further information on optional parameters is provided in Optional Parameters.
The third and final main input mode on GNAT is the GenBank input mode. Although there are four input tabs, this is the last tab that uses the main GNAT pipeline. This mode accepts GenBank files containing the data for GNs of interest as input. The maximum accepted file size is 5 MB, far above any conceivable GenBank GN file. Users may upload up to 50 files here, however we suggest uploading less than 30 files, as the time to generate the visualization scales exponentially with the number of genes (and thus GNs) provided, as does the size of the visualization file. The GenBank files uploaded here do not need to have been generated by GNAT, however uploaded files should have less than 61 (ideally 31) genes to obtain a visually-appealing result in a timely manner. This input mode performs only the final steps of the pipeline: (4) GN annotation, and (5) visualization of the annotated GN cluster. Hierarchical clustering is performed within the visualization software to automatically organize the GNs in a sensible manner.
This input mode visualizes all of the provided GNs in a single visualization file, which can be useful to highlight syntenic patterns across diverse GNs, from one or multiple jobs and genome databases. Users may optionally upload a label file to automatically annotate the visualized GNs, and may select a label database to annotate any detected defense and/or anti-defense genes. Due to the limited amount of the pipeline used, the optional parameters for this mode are limited to these aforementioned annotation-related arguments.
The Utilities tab does not use the main GNAT pipeline. Instead, it was created to provide a user-friendly way for users to perform common tasks external to the main pipeline which would otherwise be cumbersome or require command-line experience. Currently, the only task supported by the utilities tab is the merging of label files (described in Annotations), allowing users to upload several label files from previous jobs and merge them into one master label file which can be used as input to subsequent jobs or visualizations.
We plan to add other functionalities to the Utilities tab in the future, such as the ability to trim flanking genes from a GN in a GenBank file and modify the annotations within the GN permanently.
To streamline the user experience, we provide several pre-computed genomic databases on GNAT for users to perform the PSI-BLAST homology searches on. The “Database” parameter on the FASTA Sequence and PSI-BLAST Output input pages allow users to select one of these databases. The smallest database, which contains viral genomes, is selected by default. The databases range from a very large combined bacterial and viral database, to a fungal genomes database, to several Genome Taxonomy Database (GTDB) databases containing bacterial and archaeal genome data. All of the available databases, aside from the GTDB databases, were downloaded from assembly summary files on NCBI’s FTP website (ftp://ftp.ncbi.nih.gov/genomes/genbank/). A summary of the main available databases, and their sizes, is provided in the table below:
| Database Name | Size (GB) | Number of Genomes |
|---|---|---|
| Bacterial | 10,500 | 1,535,232 |
| Viral | 12.6 | 240,682 |
| Viral Bacterial | 6.96 | 1,775,913 |
| Fungal | 405 | 22,376 |
| GTDB Archaeal | 31.9 | 17,150 |
| GTDB Bacterial | 3,170 | 716,628 |
| GTDB Combined | 735 | 727,778 |
Due to the very large size of the main bacterial database, we constructed several sub-databases from it. We constructed 20 smaller databases, each of which represent one of the 20 most-prevalent genera from the main bacterial database. The genera databases are summarized below:
| Genus | Size (GB) | Number of Genomes |
|---|---|---|
| Salmonella | 1710 | 462,896 |
| Escherichia | 759 | 210,095 |
| Klebsiella | 196 | 51,450 |
| Staphylococcus | 172 | 89,086 |
| Listeria | 131 | 54,762 |
| Campylobacter | 118 | 85,213 |
| Pseudomonas | 107 | 27,646 |
| Shigella | 98.4 | 29,784 |
| Vibrio | 65.0 | 19,503 |
| Enterococcus | 59.5 | 28,475 |
| Streptococcus | 53.3 | 38,484 |
| Acinetobacter | 51.3 | 17,368 |
| Clostridioides | 47.9 | 16,557 |
| Bacillus | 29.9 | 8,946 |
| Enterobacter | 27.0 | 8,016 |
| Mycobacterium | 21.6 | 8,561 |
| Candidatus | 15.0 | 19,492 |
| Bacteroidales | 4.16 | 6,345 |
| Clostridia | 4.12 | 10,245 |
| Lachnospiraceae | 4.09 | 6,985 |
In addition to the genome databases we also constructed annotation/label databases. These are involved in the annotation of genes within the GNs, and not the actual identification and extraction of GNs. They are described in Annotations, we mention them here due to any confusion their being named “databases” may cause.
In addition to the database selection parameter, several other optional parameters are available to modify within the various input modes. These parameters are found at the bottom of the main input tabs and are divided into several categories. The categories of optional parameters available for each input mode vary slightly, depending on what portions of the pipeline the selected input mode runs. The FASTA Sequence input mode, for example, has all of the optional parameters listed below, while the GenBank Files mode only has the parameters under the “Dynamic Labelling” category. As the Utilities tab does not run a section of the main pipeline, it has no optional parameters. In the following subsections, each of which correspond to a category of parameters, we will detail the parameters in that section, what they affect, their default values and bounds, and which input modes they are available for.
The search, or source, category contains only one parameter, the genomic database to use. For the FASTA Sequence input mode, this category is called “Search”, since the database selected is searched for homologs. Meanwhile, when the selected input mode is PSI-BLAST Output, the category is called “Source”, since the selected database should correspond to the source of the PSI-BLAST matches and is used to extract and build the GNs corresponding to those matches. The default value is the viral genomes database, as it is the smallest database available on GNAT and thus runs the fastest. As of writing, there are 27 genomic databases to choose from, covering a broad range of taxa. The full details of the available databases, and thus the options for this parameter, can be found in Genome Databases.
The PSI-BLAST category is only found under the FASTA Sequence input tab, and has two associated parameters: “E-value” and “Number of iterations”. As the name of the category implies, both of these parameters affect the PSI-BLAST homology search step of the pipeline.
The “E-value” parameter allows users to modify the e-value cutoff used by PSI-BLAST. The default value is 0.01, and we allow users to enter values from 0 to 1. A lower e-value results in more closely related matches, while a larger e-value will allow for the detection of less similar, more distant homologs, however a larger e-value also increases the risk of detecting spurious matches.
The “Number of iterations” parameter allows users to modify the number of iterations performed by PSI-BLAST. The default number of iterations performed is 4, and we allow values from 1 to 6. Setting this to 1 will make the homology search behave the same way as BLASTp. Increasing the number of iterations allows for the detection of more distant homologs, but also increases the risk of spurious matches; increasing this number also significantly increases the time of the PSI-BLAST search step.
The Output Sorting category contains parameters to sort GNs based on characteristics of their PSI-BLAST match protein compared to the query. The parameters in this category are found under both the FASTA Sequence and PSI-BLAST Output input modes. After extracting the GNs around the match proteins and filtering them for redundancy, but before clustering them, all of the GNs are copied and split into two groups. One group, the “all non redundants” group, is clustered as is, however the other group is filtered into subcategories which may be more biologically relevant. These subcategories consist of above/below a percent identity (PID) threshold, and within/outside a length threshold. The parameters in this category allow users to specify the thresholds at which the GNs are sorted into the aforementioned subcategories.
The PID threshold, which defaults to 0.30, or 30%, controls which GNs fall into the above and below PID threshold groups. GNs whose match protein shares at least 30% identity with the query protein are put in the above PID group, and those that are below 30% identity with the query are put in the below PID group. This threshold was designed to separate matches that are very likely homologous to the query from those that are more spurious, hence the default of 0.30. However, we allow users to input values from 0.00 to 1.00 here, so the group names are more generic.
The length threshold, which defaults to 0.20, or 20%, controls which GNs fall into the within and outside size groups. GNs whose match protein length is within 20% of the length of the query protein are put in the within size group, and the others are put in the outside size group. This threshold was designed to separate fusion proteins from non-fusion proteins. We allow users to input values from 0.00 to 1.00 here as well.
The Clinker & Clustermap.js category contains parameters that affect the composition of the GN visualizations, which are generated with a customized version of Clinker & Clustermap.js. This category is found under both the FASTA Sequence and PSI-BLAST Output input modes. The only parameter currently in this category is “Number of flanking genes”. This parameter allows users to specify the maximum number of genes on either side of the PSI-BLAST match gene to extract when building the GNs. Thus, in the visualizations it affects how wide the GN tracks are. We say it allows users to specify the maximum number of genes on either side of the match because fewer genes may be extracted; for example, if the match is near the start or end of the source GenBank file then only the genes up to the start/end of the file will be extracted, which may be less than what the parameter was set to.
By default, the number of flanking genes is set to 15, so a maximum of 31 genes can be present in a GN (15 upstream + 15 downstream + match). We allow users to select from 0 to 30 flanking genes. Note that increasing the number of flanking genes will increase the time to generate the visualizations, as well as the size of the files themselves.
The Dynamic Labeling category contains parameters that affect the gene annotations. More information on gene annotations can be found in Annotations. The optional parameters in this category are available under all three of the main input modes: FASTA Sequence, PSI-BLAST Output, and GenBank Files. This category contains the “Label file” option and the “Select provided label database” option.
The label file option allows users to upload a label file (.csv or .label file extension) from a previous job, the “Utilities” tab, or one that was manually customized in a program such as a spreadsheet editor. The uploaded label file will be expanded with PSI-BLAST matches if the selected input mode was FASTA Sequence or PSI-BLAST Output. This label file is then used to annotate genes within the GN visualizations. By default, this parameter is blank, however note that for the FASTA Sequence and PSI-BLAST Output input modes, a label file is generated using the PSI-BLAST matches.
The provided label database option allows users to use one of the label databases provided on GNAT to label the genes in their job. The label databases are essentially very large label files that were optimized for faster searching to allow users to label genes with large datasets. If genes in the job match a gene from the label database, the job’s label file is expanded (or created in the case of the GenBank Files input mode) with that match. Thus, the resulting label file contains only matches present in your job, rather than the entire dataset. Users may select either the prokaryotic defense systems dataset, the anti-CRISPR protein dataset, or the combined dataset with annotations from both. By default, no labeling database is selected.
Gene annotations within the visualized GNs is one of GNAT’s major features. These annotations may come from three different sources: NCBI via annotations within the GenBank files containing the GNs, the PSI-BLAST homology searches, and label files/databases, which may be user defined.
The NCBI annotations come from the GenBank files that the GNs are built from. The ability to display these annotations within the GN visualizations is a feature of Clinker & Clustermap.js, and is not unique to GNAT. However, we mention them here to prevent confusion as to where the non-PSI-BLAST/label file annotations come from. These annotations include the “product” and “protein_id” label types.
Label files, by default, contain only the PSI-BLAST annotations. The default label file consists of a header line followed by label lines, each of which contain three comma-delimited columns. The header line looks like: “#All_Accessions,Match_Label,Match_E_Value”. It always must begin with a pound sign (#) and describes the names of the columns in the file. A valid label file must always have the first three columns named “All_Accessions”, “Match_Label”, and “Match_E_Value”, in that order. The all accessions column contains the protein accessions of each protein to be labelled, the match label column contains the label to be associated with the protein accession, and the match e-value column contains the e-value of the PSI-BLAST match, if applicable. In practice, the first column contains the accessions of all the PSI-BLAST matches detected, the second column contains the “name” of the query protein, and the third contains the e-value of the match. This match e-value is used when expanding existing label files in the event of two different query proteins matching the same subject protein. In this case, the match label with the lower e-value is associated with the protein accession.
The name of the query protein is extracted as the first word of the FASTA header line; the first word is defined as the sequence of characters immediately following the greater-than (>) symbol at the start of the header line, and preceding any white-space characters (e.g., space, tab, newline). If a multi-word label is desired, use underscores rather than spaces.
Label files may be expanded automatically, by uploading them as an optional argument to a new job, or by combining two or more label files via the “Utilities” tab. They may also be expanded or modified manually, by downloading the file and modifying it in a text or spreadsheet editor, such as Microsoft Excel.
If additional columns are added to a label file, “tier-labelling” mode will be enabled. This mode will add the names of the new columns (from the header line) to the tier-labelling dropdown menu within the GN visualizations. Any genes labelled under these columns will be automatically re-coloured if the tier is selected from the dropdown. Such columns are also added automatically if a label database is selected (and matches are detected).
Label databases are essentially very large label files which have been optimized for searching so that genes can be annotated using large datasets. Two unique label databases are available on GNAT: a prokaryotic defense systems dataset, and an anti-CRISPR proteins dataset. Alongside these two databases is a combined dataset containing the annotations from both. The defense systems data is sourced from DefenseFinder, which was then expanded for more coverage using NCBI’s identical protein groups (IPG) database. Meanwhile, the anti-CRIPSR (Acr) protein dataset comes from Bondy-Denomy’s “A Unified Resource for Tracking Anti-CRISPR Names” database. Due to the relatively small number of Acr/Aca proteins, this dataset was expanded using PSI-BLAST searches against our combined bacterial and viral genomes database for each protein in the dataset. The expansion of these datasets was necessary, as gene annotations are performed using the protein accession of the match proteins. If only one example protein was available for each match label, then only one protein (that one) could ever be labelled. By expanding the datasets with identical proteins and homologs, respectively, we enabled the rapid annotation of many defense/anti-CRISPR proteins.
Any matches to label database proteins will expand the resulting job’s label file with tier-labelling columns, which enable users to recolour genes which were found to encode defense system or anti-CRISPR proteins, as well as retaining the ability to display the usual text annotations.
Upon job submission, the input is validated. If any errors are detected, users are redirected to the input page with an error message. If the input was valid, then users are redirected to the job loading page. When the job has finished processing successfully, the job loading page will reload and direct users to their job output. However, to access job output after navigating away from the loading page, the Job Retrieval page, accessible via the “Jobs” tab on GNAT, is necessary.
On the loading page, users are presented with a job identification number, called the Job ID, along with a job password. The Job ID consists of four digits, followed by an underscore and an additional three alphanumeric characters. The first four digits correspond to the date the job was submitted in MMDD (month-month-day-day) format; the Job ID for a job submitted on March 15, for example, would begin with 0315. The three characters following the underscore are random, as is the job password.
To retrieve a job, navigate to the Job Retrieval page at https://gnat.usask.ca/job. At the top of the page is a Job Retrieval container, with a text input box. The ID of the job may be entered in that box to be redirected to the job output page. Upon entering a valid Job ID, users will be prompted for their job password before gaining access to the job output.
Also on the job retrieval page are links to sample jobs for users to explore and familiarise themselves with the shape of GNAT’s output. Below the Job Retrieval container is a Job Status section which lists the IDs of current and previously-run jobs, along with their progress or status if they have finished.
An overview of the basic interactions possible within the output browser is provided in the Quick Start Guide section. Here, we will provide additional details on GNAT’s output file structure along with the interactive features possible within the GN visualizations. The output file structure we detail here refers only to jobs generated via the FASTA Sequence or PSI-BLAST Output input modes, as the other two modes have fairly simple outputs. Each job results in a main job output directory, which shares a name with the job ID, and is what you are presented with to explore. Upon first loading the job output, you will be presented with an Output Dashboard. This dashboard consists of a grid of cards containing previews of the GN visualizations along with the name of their associated file. Clicking on a card will open the corresponding visualization file in the main output viewer. Alternatively, to access the main output viewer, users may click on the grid icon at the top of the page. This button may be clicked again to toggle the dashboard view back on.
On the main output view, the output directory is auto-expanded up to the first subdirectory containing a GN visualization. This subdirectory is usually the above PID threshold, within-size threshold subdirectory, however it may be different if there were no matches within that subcategory. Clicking on the GN visualization file, which is the filename with a DNA icon, will open it in the file viewer on the right side of the screen. In the file viewer, users can interact with HTML files as if they were downloaded on their computer, however any changes will not be saved (for example changing the selected annotation display type). These interactive HTML files include the GN visualization files and the Krona taxonomic distribution files. Other files, such as the text-based label files, PSI-BLAT output files, FASTA files, and GenBank files are not interactive and are read-only. To modify the text-based files, they must be downloaded. Above the file display is a file header, which contains the name of the open file, along with buttons to download, favourite, or close it.
Within the GN visualizations, users may perform any interactions allowed by the default version Clinker & Clustermap.js, including: zooming and panning the screen, moving, trimming, resizing, and flipping GN loci tracks, toggling various GenBank label types, writing custom gene labels, and manually re-colouring gene homology groups. With our customized version, PSI-BLAST and label file annotations are available and are automatically displayed. Selecting a tier-labeling column (if available, e.g., if a label database was used) will automatically recolour any genes matching the label tier, rather than using the default homology groupings. Our custom version also displays the most prevalent product annotations for each homology group, and allows users to highlight genes in a given group by hovering the mouse over the group name. All GNs in each visualization are automatically flipped and aligned on the PSI-BLAST match genes to facilitate visual syntenic comparisons. We also allow users to upload a label file directly to a GN visualization, which will add “Dynamic” labels to the label type dropdown, allowing users to re-annotate a GN visualization without re-generating it.
Favouriting a file will add it to a “Favourites” shortlist at the top of the directory browser, which persists across sessions. Jobs will generate a summary statistics file, which highlights broad annotation patterns across the visualized GNs, and also contains a shortlist of GNs which have more annotated genes than expected. The visualization files, each of which corresponds to a cluster of GNs, are organized into four subcategories, based on how their PSI-BLAST match gene was filtered via the PID and size thresholds: above PID, within size; above PID, outside size; below PID, within size; and below PID, outside size. More on these thresholds can be found in Optional Parameters. Further, an unfiltered copy of all non-redundant GNs is clustered and visualized separately in the “all_non_redundants” directory to preserve any patterns that may have been missed due to the filtering. The “redundants” directory contains the GenBank files associated with redundant, or duplicate, GNs, with the “.map” mapping file containing a mapping of redundant GNs to their non-redundant representative.
The other interactive visualization files generated by our pipeline are the Krona taxonomy distribution files, which are essentially interactive sunburst plots. We generate one of these taxonomy distribution visualizations at every clustering and filtering step of the pipeline, to visualize how the distribution of the organisms the GNs were sourced from may change in response to, for example, the PID filter. These visualizations may help users identify how certain gene patterns evolved, either vertically or horizontally.
The interactive features of the GN visualizations may be slow on some browsers. We find Firefox or Google Chrome to be most responsive. If the plots remain unresponsive, it may be due to their size; large visualization file sizes have reduced responsiveness. More genes/GNs in a plot will increase the file size. Further, plots with many similar GNs, and thus more gene-gene links, will be larger, due to the additional link objects.
If your job is taking a long time to run, several reasons could be to blame. If several jobs are currently running on the server, the job could be waiting in the queue for a worker to begin it. To diagnose this case, check the “Loading Information” section of the loading screen: if there is only a “Job Receive” message and no “Starting…” message, then your job is in the queue and you will have to wait for other jobs on the server to complete and free up a worker to start your job. If your job has started, but appears stuck, note that the PSI-BLAST search step, GN clustering step, and GN visualization steps can all take quite some time. In particular, if a large database such as the combined bacterial-viral database, was selected, the PSI-BLAST search can take hours to days. If the loading information does not suggest that the job is simply working on one of these long-running steps, or if you think something went wrong and the job is not progressing, send an email for support to gnat@usask.ca with a descriptive subject line. In general, to reduce job runtime, select smaller databases (detailed in Genome Databases), and/or input fewer sequences. Although we allow up to 5 sequences for the FASTA Sequences input mode, we suggest submitting a separate job for each sequence for the most rapid results.
If you detect a bug, require support, or have a question not answered on this page or our paper, please send an email to gnat@usask.ca with a descriptive subject line.
For an overview of the capabilities and methodology of GNAT, GNAT: An Interactive Web Tool for Gene Neighbourhood Analysis (bioRxiv).
For a very in-depth description of GNAT and GNAT-CLI (AcrVis), AcrVis and GNAT - Computational Tools for the Exploration and Annotation of Genomic Neighbourhoods (HARVEST).
MIT License
Copyright © 2026 Nolen Timmerman
The following license applies to all original code in this repository. This
repository also incorporates third-party software under separate license
terms; see THIRD_PARTY_LICENSES.txt for details.
Permission is hereby granted, free of charge, to any person obtaining a copy
of this software and associated documentation files (the “Software”), to deal
in the Software without restriction, including without limitation the rights
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
copies of the Software, and to permit persons to whom the Software is
furnished to do so, subject to the following conditions:
The above copyright notice and this permission notice shall be included in all
copies or substantial portions of the Software.
THE SOFTWARE IS PROVIDED “AS IS”, WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
SOFTWARE.
MIT License
Copyright (c) 2019 Cam Gilchrist
Permission is hereby granted, free of charge, to any person obtaining a copy
of this software and associated documentation files (the "Software"), to deal
in the Software without restriction, including without limitation the rights
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
copies of the Software, and to permit persons to whom the Software is
furnished to do so, subject to the following conditions:
The above copyright notice and this permission notice shall be included in all
copies or substantial portions of the Software.
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
SOFTWARE.
PURPOSE
Krona is a flexible tool for exploring the relative proportions of
hierarchical data, such as metagenomic classifications, using a
radial, space-filling display. It is implemented using HTML5 and
JavaScript, allowing charts to be explored locally or served over the
Internet, requiring only a current version of any major web
browser. Krona charts can be created using an Excel template or from
common bioinformatic formats using the provided conversion scripts.
COPYRIGHT LICENSE
Copyright © 2011, Battelle National Biodefense Institute (BNBI);
all rights reserved. Authored by: Brian Ondov, Nicholas Bergman, and
Adam Phillippy
This Software was prepared for the Department of Homeland Security
(DHS) by the Battelle National Biodefense Institute, LLC (BNBI) as
part of contract HSHQDC-07-C-00020 to manage and operate the National
Biodefense Analysis and Countermeasures Center (NBACC), a Federally
Funded Research and Development Center.
Redistribution and use in source and binary forms, with or without
modification, are permitted provided that the following conditions are
met:
* Redistributions of source code must retain the above copyright
notice, this list of conditions and the following disclaimer.
* Redistributions in binary form must reproduce the above copyright
notice, this list of conditions and the following disclaimer in the
documentation and/or other materials provided with the distribution.
* Neither the name of the Battelle National Biodefense Institute nor
the names of its contributors may be used to endorse or promote
products derived from this software without specific prior written
permission.
THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS
"AS IS" AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT
LIMITED TO, THE IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR
A PARTICULAR PURPOSE ARE DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT
HOLDER OR CONTRIBUTORS BE LIABLE FOR ANY DIRECT, INDIRECT, INCIDENTAL,
SPECIAL, EXEMPLARY, OR CONSEQUENTIAL DAMAGES (INCLUDING, BUT NOT
LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR SERVICES; LOSS OF USE,
DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER CAUSED AND ON ANY
THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY, OR TORT
(INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
TRADEMARK LICENSE
KRONA™ is a trademark of the Department of Homeland Security, and use
of the trademark is subject to the following conditions:
* Distribution of the unchanged, official code/software using the
KRONA™ mark is hereby permitted by the Department of Homeland
Security, provided that the software is distributed without charge
and modification.
* Distribution of altered source code/software using the KRONA™ mark
is not permitted unless written permission has been granted by the
Department of Homeland Security.
PATENTS
The Krona software is not eligible for patent because there have been
previous and open implementations of this visualization method since
the year 2000 (e.g. "Focus+context display and navigation techniques
for enhancing radial, space-filling hierarchy visualizations." Stasko,
J. and Zhang, E. InfoVis, 2000). Krona represents a reimplementation and
application of an existing method to the new domain of
metagenomics. BNBI, as the copyright holders, wish to release Krona
freely and openly as a service to the bioinformatics community.
POINT OF CONTACT
Todd Harrington
General Counsel
Battelle National Biodefense Institute
harringtont@nbacc.net